
News & Insights
Local LLMs and Data Sovereignty for Malaysian Businesses

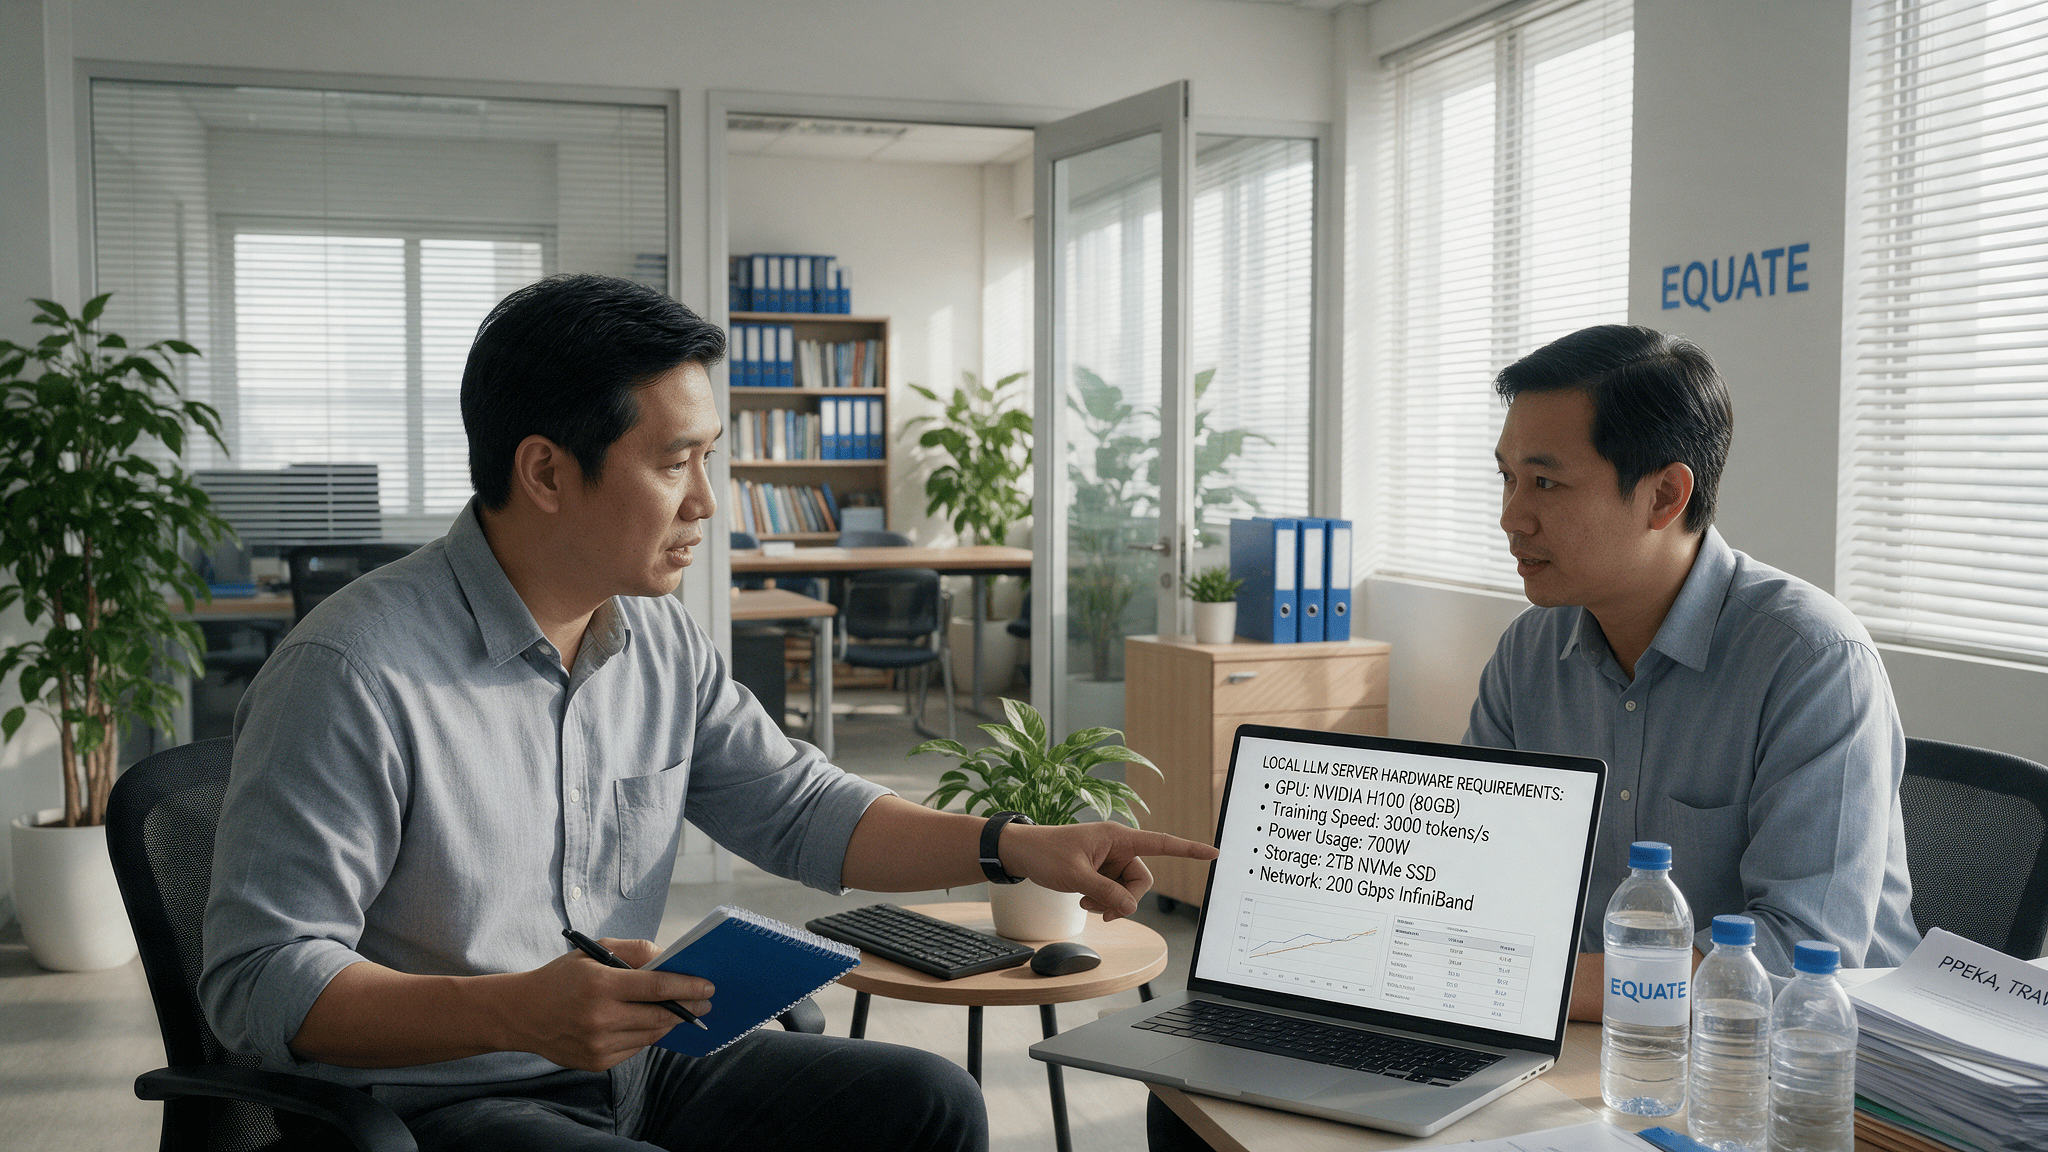
A Local LLM is a large language model that runs on infrastructure your organisation controls, rather than on a service you send your data to. For a growing number of Malaysian organisations that distinction decides whether an AI project can proceed at all, which is why it sits at the centre of how our data and AI practice approaches regulated work.
This guide explains what a Local LLM is and is not, why some data cannot be sent to a public model, how residency, sovereignty and control differ, what you give up by running your own, and a way to decide which data stays in-country.
What a Local LLM Is
A Local LLM is a model deployed on-premises or on local infrastructure the organisation controls, so that prompts, documents and outputs stay inside its own environment. Nothing is sent to an external provider for processing.
Three things follow from that, and they are the practical reasons organisations choose it.
- The data does not leave: Records used in a prompt, and the documents the model is grounded in, remain where your other systems already keep them. There is no transfer to assess and no third-party retention policy to negotiate.
- You control the model version: It changes when you decide it changes. For a process that has been validated and documented, a model that silently updates underneath it is a compliance problem rather than a feature.
- The audit trail is yours: Prompts, retrieved sources, outputs and approvals can be logged in systems you already run and retain for as long as your own policies require.
What a Local LLM is not: it is not a private tenancy on someone else’s AI service. Cloud deployment models are a separate question, and a private or in-country cloud can be the right answer for many workloads. The distinguishing question for AI is narrower. When the model runs, whose infrastructure is the data sitting on, and who can reach it.
Why Some Data Cannot Go to a Public Model
Sending records to an external AI service is a transfer of that data, and four separate constraints tend to apply in Malaysia.
The PDPA’s cross-border rules changed in 2025. The amended Section 129 of the Personal Data Protection Act 2010 came into force on 1 April 2025. The previous whitelist regime, under which the Minister gazetted approved destinations, was removed, and responsibility for judging whether a receiving jurisdiction offers adequate protection now sits with the data controller. On 29 April 2025 the Personal Data Protection Commissioner issued guidelines on cross-border personal data transfer setting out how each condition in Section 129 may be relied on and what evidence should be kept. In practice that means your organisation, not your AI vendor, owns the assessment.
Sector regulation adds its own expectations. Financial institutions sit under Bank Negara Malaysia’s technology risk requirements, including for arrangements with third-party service providers. Healthcare data carries patient confidentiality obligations on top of the PDPA, and public sector work often carries residency conditions written into the contract.
Client and contractual confidentiality. Professional services firms, contract manufacturers and anyone handling another company’s designs or customer lists usually have contractual terms that predate generative AI and are broad enough to cover it.
Your own intellectual property. Source code, pricing models, formulations and negotiation positions are not personal data, so no regulator protects them. The commercial exposure of putting them into an external service is a decision the business has to make on its own terms.
Residency, Sovereignty and Control Are Three Different Things
These get used interchangeably in vendor conversations, and they answer different questions.
- Residency is where data is physically stored and processed. It is the easiest to verify and the easiest to overstate, because a service may keep primary data in-country while support access, logging or model inference happens elsewhere.
- Sovereignty is whose law applies to the data and who can compel its disclosure. Data held in Malaysia by an entity subject to another country’s jurisdiction may still be reachable through that jurisdiction’s legal process. This is a question for your legal team about the operating entity, not a technical specification.
- Control is who holds the credentials, the encryption keys and the ability to grant access. It is the most useful of the three to pin down, because it determines what happens on a day when the vendor relationship ends or a request for access arrives.
Ask a provider all three questions separately. A confident answer to the residency question is often used to close down the other two.
Local LLM vs Public Cloud AI: The Trade-offs
Running your own model is a real cost, and the honest case for it rests on constraints rather than on performance.
| Dimension | Public cloud AI service | Local LLM |
| Model capability | Access to the largest current models, updated continuously | Typically smaller open-weight models, chosen and pinned by you |
| Data exposure | Data leaves your environment; retention and access governed by the provider | Data stays within your environment |
| Cost shape | Operating cost that scales with usage, low to start | Upfront investment in hardware and setup, then largely fixed |
| Model updates | Managed for you, sometimes without notice | Your decision, and your work to test and deploy |
| Operational burden | Minimal | Real: capacity, monitoring, patching, model lifecycle |
| Audit and evidence | Depends on what the provider exposes | Complete, in systems you already operate |
| Best suited to | Low-sensitivity, high-variety tasks where capability matters most | Bounded, repeatable processes on sensitive data |
Most organisations end up with both. The useful framing is not which is better but which data belongs on which, and that is a classification exercise rather than a technology choice.
Deciding What Stays In-Country
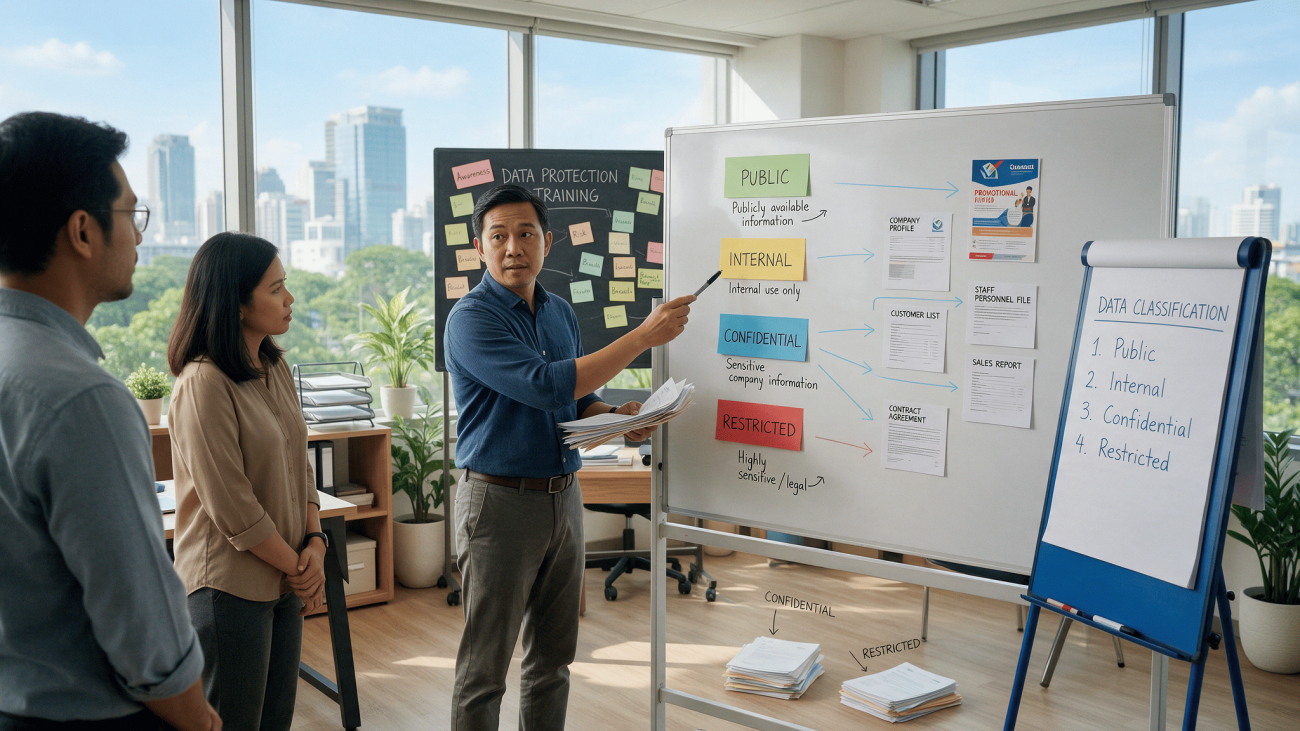
Classify the data before choosing the platform. Four tiers are usually enough, and most organisations find the top tier is smaller than they feared.
| Tier | Typical content | Where it can be processed |
| Public | Published material, marketing copy, public documentation | Any service, no restriction |
| Internal | Process documents, internal drafts, non-personal operational records | External services acceptable with contractual controls |
| Confidential | Customer records, employee data, commercial terms, client deliverables | In-country processing, or an assessed transfer with documented evidence |
| Regulated or restricted | Banking transaction data, patient records, government case data, anything with a contractual residency clause | Infrastructure the organisation controls |
Then work through four questions for each candidate use case. Does the process touch a tier that cannot leave. If it does, can the task be redesigned so the sensitive fields never enter the prompt, for example by masking identifiers. If not, does the task need frontier-model capability, or would a smaller model grounded in your own documents do it. And who signs off that the classification is right, because this decision should not sit with the project team alone.
What Running a Local LLM Requires
It is an infrastructure commitment, not a licence purchase. Budget for six things.
- Hardware sized to the workload: Inference for a bounded internal use case is modest. Sizing follows from expected concurrency and response time, so agree those first.
- A model and its licence: Open-weight models carry licence terms that vary in what commercial use they permit. Check them the way you would any other software licence.
- Grounding in your own content: Most enterprise value comes from retrieval over your documents and records rather than from the model’s general knowledge. That means a current, permissioned source of truth to retrieve from.
- Evaluation: A test set with human-scored answers, run before go-live and repeated after any change. Without it, quality is an opinion.
- Access control and logging: The same controls as any system holding that data class, including who can query it, what is retained and for how long.
- A lifecycle owner: Someone responsible for model updates, dependency patching and capacity as usage grows.
Where Strateq Fits
Our position on this is straightforward: where sensitive data cannot leave the organisation, the answer is a Local LLM deployed on the customer’s own on-premises or local infrastructure, not a hosted service the data is sent to.
That is how our own AI products are built. The AI operations agent triages infrastructure events with an on-premises model, the credit memo agent runs risk scoring and policy checks with self-hosted models and human checkpoints, and the training and service desk assistants answer from the organisation’s own content rather than the public internet. Where the surrounding process crosses several systems, the orchestration and on-premises AI positioning sits with our business process automation platform, which is built to let an organisation control where its data lives and which model it uses.
For organisations that want in-country infrastructure without operating a facility themselves, we have run our own data centres in Malaysia since 1989, certified to ISO/IEC 27001:2022 and ANSI/TIA-942, where our colocation, disaster recovery and business continuity services are delivered.
If you are working out which of your use cases can use a public service and which cannot, start with the classification table above and bring the disputed rows to our Data & AI team.